Introduction
Wanaku aims to provide unified access, routing and resource management capabilities for your organization and your AI Agents.
Understanding What Is Wanaku
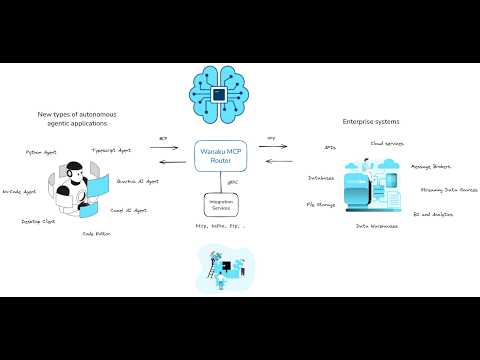
The Wanaku MCP Router is an integration service designed to securely connect AI agents with various enterprise systems and cloud services. It acts as a central hub that manages and governs how agents access specific resources and tools, effectively proxying and filtering capabilities exposed to Large Language Models (LLMs).
The Wanaku MCP Router itself does not directly host tools or resources; instead, it acts as an integration service that connects AI agents with external resources and tools, including enterprise systems and cloud services. It manages and governs access between agent types and specific resources, proxying and filtering available capabilities to agents and their LLM

Wanaku connects to downstream MCP servers that provide specific functionalities to the Wanaku MCP Router.
These downstream MCP servers enable communication with various systems, such as Kafka services, message brokers, cloud services (AWS, Azure, Google, etc.), databases and a wide range of enterprise systems, including Workday and Salesforce, without directly containing the tools or resources.
Furthermore, Wanaku features an MCP-to-MCP bridge, which allows it to act as a centralized gateway or proxy for other MCP servers that use HTTP as the transport mechanism. This capability enables Wanaku to aggregate and effectively "hide" multiple external MCP servers, simplifying management and increasing the overall functionality of a Wanaku instance. Wanaku is an open-source project and is licensed under Apache 2.0.
Meet Wanaku
If you haven't seen it already, we recommend watching the Getting Started with Wanaku video that introduces the project, and introduces how it works.
NOTE
Also check the Getting Started from the demos repository.
Using Wanaku
Using Wanaku MCP Router involves two key actions:
- Forwarding other MCP servers via the MCP forwarder
- Adding new downstream MCP servers
Tools and resources are provided by MCP servers registered with the router. When you add an MCP server, its tools and resources become automatically available to agents using Wanaku.
Forwarding other MCP servers via the MCP forwarder
Wanaku can act as a central gateway or proxy to other MCP servers that use HTTP as the transport mechanism. This feature allows for a centralized endpoint to aggregate tools and resources provided by other MCP servers, making them accessible as if they were local to the Wanaku instance.
Adding new downstream MCP servers
This refers to extending the router's functionality by integrating with various external systems.
Wanaku leverages Quarkus and Apache Camel to provide connectivity to a vast range of services and platforms. This allows users to create custom services to solve particular needs. These services can be implemented in any language that supports the Wanaku communication protocol.
NOTE
It is also possible to create and run services in Java and other languages, such as Go or Python, although the process is not entirely documented at the moment.
Preparing the System for Running Wanaku
Security in Wanaku involves controlling access to the management APIs and web interface while ensuring that only authorized users can modify tools, resources, and configurations. Wanaku also ensures secure access to the MCP tools and resources.
Wanaku uses Keycloak for authentication and authorization. A Keycloak instance is required when running Wanaku with authentication enabled. This section covers the basics of getting Keycloak ready for Wanaku for development and production purposes.
NOTE
Wanaku can also run without authentication by setting wanaku.http.auth=none. This is useful for local development, testing, or air-gapped environments where an identity provider is not available. See Running Without Authentication for details.
Keycloak Setup for Wanaku
Choose the setup that matches your environment.
- Local Development: Use Podman for a quick, local instance.
- OpenShift Deployment: Follow these steps for a cluster environment.
Option 1: Local Setup with Podman
This method is ideal for development and testing on your local machine.
Starting the Keycloak Container
First, run the following command in your terminal to start a Keycloak container. This command also sets the initial admin credentials and maps a local volume for data persistence.
podman run -d \
  -p 127.0.0.1:8543:8080 \
  -e KC_BOOTSTRAP_ADMIN_USERNAME=admin \
  -e KC_BOOTSTRAP_ADMIN_PASSWORD=admin \
  -v keycloak-dev:/opt/keycloak/data \
  quay.io/keycloak/keycloak:26.7 start-dev
-p 127.0.0.1:8543:8080: Maps port8543on your local machine to the container's port8080. By default, Wanaku expects Keycloak on port8543.-e ...: Sets the default admin username and password. Change the password for any non-trivial use case.-v keycloak-dev...: Creates a persistent volume namedkeycloak-devto store Keycloak data.
Option 2: Deploying to OpenShift or Kubernetes
If you are deploying Wanaku in OpenShift or Kubernetes, you can follow these steps to get an entirely new Keycloak setup up and running. If you already have a Keycloak instance, you may skip the deployment section and jump to importing the realm.
Deploying Keycloak
Apply the pre-defined Kubernetes configurations located in the deploy/auth directory. This will create all the necessary resources for Keycloak to run.
IMPORTANT
Before applying, review the files and be sure to change the default admin password for security.
NS=$(kubectl config view --minify -o jsonpath='{..namespace}')
DOMAIN=$(oc get ingresses.config.openshift.io cluster -o jsonpath='{.spec.domain}')
KC_HOST="keycloak-$NS.$DOMAIN"
cat deploy/auth/keycloak.yaml | sed "s/KEYCLOAK_HOST/https:\/\/$KC_HOST/"| kubectl create -f -
Expose the Keycloak service outside the cluster.
Note that the service is exposed with a self-signed certificate, for development purposes only.
- Minikube
cat deploy/auth/keycloak-ingress.yaml | sed "s/KEYCLOAK_HOST/keycloak.$(minikube ip).nip.io/"| kubectl create -f -- OpenShift
kubectl apply -f deploy/auth/keycloak-router.yamlImporting the Wanaku Realm Configuration (via Wanaku Keycloak Admin CLI)
The simplest way to import the realm configuration is using the wanaku-keycloak-admin CLI. You can set admin credentials once via environment variables:
export WANAKU_ADMIN_USERNAME=admin
export WANAKU_ADMIN_PASSWORD=admin
wanaku-keycloak-admin realm create
This imports the default realm configuration from deploy/auth/wanaku-config.json. You can specify a custom configuration file with --config /path/to/realm.json and a custom Keycloak URL with --keycloak-url. Also, in case the keycloak server is in https with a self-signed certificate, then you have to import the realm config file with the Keycloak UI or execute the deploy/auth/configure-auth.sh script.
To get the keycloak server:
- Minikube :
echo "https://"$(kubectl get ingress keycloak -o jsonpath='{.spec.rules[0].host}') - OpenShift:
echo "https://"$(kubectl get route keycloak -o jsonpath='{.spec.host}')
Importing the Wanaku Realm Configuration (via Shell Script)
Alternatively, Wanaku comes with a script that simplifies importing the realm configuration into keycloak.
The script takes care to discover the Keycloak server address. You can optionally customize the keycloak URL, user and password with the following environment variables:
- set the
WANAKU_KEYCLOAK_PASSvariable to the admin password of your Keycloak instance - set
WANAKU_KEYCLOAK_HOSTto the address of your Keycloak instance (i.e.;localhostif using Podman). If in OpenShift or minikube, it already takes care to discover it.
Importing the Wanaku Realm Configuration (via Keycloak UI)
Alternatively, you may also import the configuration using Keycloak's UI, and then proceed to regenerate the service client secret.
Regenerating the Service Client Secret
Finally, for security, you must regenerate the client secret for the wanaku-service client.
- Navigate to the Keycloak Admin Console at
http://localhost:8543. - Log in with your admin credentials (admin/admin).
- Select the wanaku realm from the dropdown in the top-left corner.
- Go to Clients in the side menu and click on wanaku-service.
- Go to the Credentials tab.
- Click the Regenerate secret button and confirm. Copy the new secret to use in your application's configuration.

Running Without Authentication
Wanaku can run without authentication by setting wanaku.http.auth=none (or WANAKU_HTTP_AUTH=none via environment variable). This disables OIDC and permits access to all API endpoints, the admin UI, and MCP namespaces without requiring a Bearer token or a Keycloak instance.
This is useful for:
- Local development and testing — no need to set up Keycloak
- Air-gapped environments — where an external identity provider is not available
- Quick prototyping — get started with Wanaku immediately
Disabling Authentication
Using the CLI (default for local):
wanaku start localThe wanaku start local command automatically disables authentication, so no additional configuration is needed.
Using an environment variable:
export WANAKU_HTTP_AUTH=none
java -jar quarkus-run.jar
Using a system property:
java -Dwanaku.http.auth=none -jar quarkus-run.jarUsing Docker Compose:
A dedicated compose file is provided at deploy/docker-compose/docker-compose-noauth.yml that runs the router without Keycloak:
docker compose -f deploy/docker-compose/docker-compose-noauth.yml upIf you extend that compose file with downstream MCP servers, set WANAKU_HTTP_AUTH=none on those services as well.
WARNING
Running without authentication disables all access control. Do not use it in production environments where access control is required.
Installing Wanaku
To run Wanaku, you need to first download and install the router and the command line client.
Prerequisites
Important: Java 21 or later is required to run Wanaku. Ensure you have Java 21+ installed before proceeding with the installation.
You can verify your Java version by running:
java -versionInstalling the Command Line Interface (CLI)
Although the router comes with a UI, the CLI is the primary method used to manage the router. As such, it's recommended to have it installed.
Installing the CLI by downloading binary
The most recommended method for installing the Wanaku CLI is to download the latest version directly from the release page on GitHub
Installing the CLI via JBang
To simplify using the Wanaku Command Line Interface (CLI), you can install it via JBang.
Note: JBang requires Java 21 or later for running Wanaku CLI.
First, ensure JBang is installed on your system. You can find detailed download and installation instructions on the official JBang website.
After installing JBang, verify it's working correctly by opening your command shell and running:
jbang versionThis command should display the installed version of JBang.
Next, to access the Wanaku CLI, install it using JBang with the following command:
jbang app install wanaku@wanaku-ai/wanakuThis will install Wanaku CLI as the wanaku command within JBang, meaning that you can run Wanaku from the command line by just executing wanaku.
NOTE
It requires access to the internet, in case of using a proxy, please ensure that the proxy is configured for your system. If Wanaku JBang is not working with your current configuration, please look to Proxy configuration in JBang documentation.
PATH Configuration
If you installed the Wanaku CLI using get-wanaku.sh or the native build (make install), it is placed in $HOME/bin. Many systems do not include $HOME/bin in the default PATH, so you may need to add it manually to avoid a "command not found" error when running wanaku.
To add $HOME/bin to your PATH for the current session:
export PATH="$HOME/bin:$PATH"To persist this across sessions, add the line above to your shell configuration file:
echo 'export PATH="$HOME/bin:$PATH"' >> ~/.bashrc
source ~/.bashrc
Note: If you are using
zsh, replace~/.bashrcwith~/.zshrc.[!TIP] The
get-wanaku.shscript auto-detects your OS and architecture, downloads the latest release, verifies the checksum, and installs to$HOME/bin. You can override the install directory withWANAKU_INSTALL_DIR=/usr/local/bin.
Verify the installation:
wanaku --versionHandling HTTPS connections
Wanaku CLI may connect to either Keycloak or Wanaku MCP server, if their HTTP endpoints are protected by a server certificate (TLS) you may choose to skip the certificate checks or use the CA (Certificate Authority) that issued them on the wanaku-cli so the client can check the server certificate.
- In wanaku-cli you can skip the checks by using the
--insecureparameter, and it's going to print a warning message about it. - You can use the CA that signed the Keycloak HTTPS endpoint, by either importing it into the default Java truststore
$JAVA_HOME/lib/security/cacertsor have a particular keystore file and use the-Djavax.net.ssl.trustStoreand-Djavax.net.ssl.trustStorePasswordparameters to refer to this custom truststore.
NOTE: You can set these -D to the wanaku-cli as in this example:
java "-Djavax.net.ssl.trustStore=my-truststore.p12" "-Djavax.net.ssl.trustStorePassword=changeit" -jar quarkus-run.jar admin credentials show --admin-username=admin --admin-password=admin --keycloak-url=https://keycloak.192.168.49.2.nip.io --show-secret --client-id wanaku-serviceInstalling and Running the Router
There are three ways to run the router. They work similarly, with the distinction that some of them may come with more services by default — continue reading the documentation below for details.
IMPORTANT
For production deployments with authentication, the router needs to be configured for secure access and control of its resources. Make sure you read the section Securing the Wanaku MCP Router before running or deploying the router. For local development or testing, you can run without authentication.
Installing and Running Wanaku Locally Using "Wanaku Start Local"
You can use the Wanaku CLI to start a small/simplified local instance. After downloading the CLI, simply run wanaku start local and the CLI should download, deploy and start Wanaku with the main server, a file provider and an HTTP provider.
wanaku start localThe local runner disables authentication by default, so Keycloak is not required. The router and all downstream MCP servers will start without authentication.
If that is successful, open your browser at http://localhost:8080, and you should have access to the UI.
NOTE
You can use the command line to enable more services by using the --services option. Use the --help to see the details.
Running with the Camel Integration Capability
The Camel Integration Capability (CIC) lets you expose Apache Camel routes as MCP tools. You can supply routes in two ways: from local YAML files or from a service catalog.
Using Camel route files:
wanaku start local \
  --camel-routes file:///path/to/routes.camel.yaml \
  --camel-rules file:///path/to/rules.yaml
--camel-routes and --camel-rules must both be provided when using route files.
Using a service catalog:
wanaku start local \
  --service-catalog my-catalog \
  --service-catalog-system ftp
--service-catalog and --service-catalog-system must both be provided when using service catalogs.
NOTE
The two modes are mutually exclusive — you can use route files or a service catalog, but not both at the same time.
The --fail-fast flag (enabled by default) causes the CIC to fail immediately if route loading encounters an error. Disable it with --fail-fast=false if you want the service to start regardless.
When any CIC option is provided, the camel-integration service is automatically added to the launch list.
Installing and Running Wanaku on OpenShift or Kubernetes Using the Wanaku Operator
The Wanaku Operator simplifies the deployment and management of Wanaku instances on Kubernetes and OpenShift clusters. It automates the creation and configuration of all necessary resources, making it the recommended approach for production deployments.
NOTE
For comprehensive operator documentation including CRD field reference, deployment patterns, lifecycle management, Helm configuration, and troubleshooting, see the Kubernetes Operator Guide.
Quick Start
Prerequisites:
- Kubernetes 1.27+ or OpenShift 4.12+
kubectlorocCLI,helm3.x- Keycloak instance (see Keycloak Setup) or plan to use
wanaku.http.auth=nonefor development - Wanaku container image (optional)
Build the container image:
You can build the container image and push it to a container registry, or use a pre-built image.
There is a pre-built image in quay.io/wanaku/wanaku-barn-backend:latest
Install the operator:
kubectl create namespace wanaku
helm install wanaku-operator ./apps/wanaku-operator/deploy/helm/wanaku-operator \
  --namespace wanaku \
  --set operatorNamespace=wanaku
Deploy a router:
# wanaku-router.yaml
apiVersion: "wanaku.ai/v1alpha1"
kind: WanakuRouter
metadata:
  name: wanaku-dev
spec:
  auth:
authServer: http://keycloak:8080kubectl apply -f wanaku-router.yaml -n wanaku
kubectl wait wanakurouter/wanaku-dev --for=condition=Ready --timeout=120sDeploy capabilities:
# wanaku-capabilities.yaml
apiVersion: "wanaku.ai/v1alpha1"
kind: WanakuCapability
metadata:
  name: wanaku-capabilities
spec:
  auth:
    authServer: http://keycloak:8080
  secrets:
    oidcCredentialsSecret: wanaku-oidc-secret
  routerRef: wanaku-dev
  capabilities:
    - name: wanaku-http
image: quay.io/wanaku/wanaku-tool-service-http:latestkubectl apply -f wanaku-capabilities.yaml -n wanaku
kubectl wait wanakucapability/wanaku-capabilities --for=condition=Ready --timeout=120sTIP
Complete sample CRs are in apps/wanaku-operator/samples. For service catalog deployment via the operator, see the Operator Guide.
Installing and Running Wanaku on OpenShift or Kubernetes (Manually)
It is also possible to manually run Wanaku on Kubernetes distributions, such as OpenShift, without the operator. You can use the Helm chart directly:
Install the operator Helm chart:
shellhelm install wanaku-operator apps/wanaku-operator/deploy/helm/wanaku-operator --namespace <your-namespace>Create and apply a
WanakuRoutercustom resource for your environment (seedeploy/kubernetes/wanaku-router.yamlfor an example)Create and apply a
WanakuCapabilitycustom resource for your capabilities (seedeploy/kubernetes/wanaku-capabilities.yamlfor an example)
Configuring the Wanaku MCP Router
Wanaku is built on Quarkus and uses application.properties files for configuration. Each component ships with built-in defaults, but you can override any property at runtime in three ways:
- External file: place an
application.propertiesin aconfig/directory next to the JAR - System properties: pass
-D<property>=<value>on the command line - Environment variables: export the property name in uppercase with dots/hyphens replaced by underscores
For example, to change the HTTP port:
# Via system property
java -Dquarkus.http.port=9090 -jar wanaku-barn-backend-runner.jar

# Via environment variable
export QUARKUS_HTTP_PORT=9090
java -jar wanaku-barn-backend-runner.jar
For the full list of available properties and more details on configuration precedence, see the Configuration Guide.
Accessing the Administration Web User Interface
Wanaku also comes with a web user interface that you can access to manage the router. By default it runs on port 8080 of the host running the router.
NOTE
At this moment, some features are only available on the CLI.
When accessing the Web UI for the first time, you will be redirected to the Keycloak instance for login. Create a user and define a password.
IMPORTANT
Wanaku does not yet support fine-grained access control. All authenticated users have admin access to tools and resources. Expect this to change in future versions.
Installing and Running Downstream MCP Servers
Downstream MCP servers are standalone services that connect to the Wanaku router to provide new functionalities. They can be downloaded from the release page, deployed to OpenShift using the operator and containers or built from source.
To run a downstream MCP server, you need to configure it to connect to your Wanaku router instance and authenticate with it. This is done by setting a few essential properties.
Configuring Downstream MCP Servers
You can configure downstream MCP servers using environment variables, system properties on the command line, or by placing an application.properties file in a config/ directory next to the service JAR (see the Configuration Basics section for details on how Quarkus loads configuration).
Here are the key properties you need to set:
Router URI: Each downstream MCP server needs to know where the Wanaku router is located to register itself.
propertieswanaku.service.registration.uri=http://localhost:8080OIDC Client Credentials: Downstream MCP servers authenticate with the router using OIDC. You must provide the client secret that you previously regenerated in Keycloak.
propertiesquarkus.oidc-client.credentials.secret=your-client-secret-from-keycloakAnnounce Address (Optional): If the downstream MCP server is running in an environment where its address is not directly accessible by the router (e.g., behind a NAT or in a container), you need to specify the address that the router should use to communicate back to it.
propertieswanaku.service.registration.announce-address=your-public-address
TIP
You can check the full set of configuration available.
Running a Downstream MCP Server
Once configured, you can run the service from the command line. The following example shows how to run a downstream MCP server while overriding the configuration properties:
java -Dwanaku.service.registration.uri=http://<wanaku-router-host>:8080 \
     -Dquarkus.oidc-client.credentials.secret=<your-client-secret> \
     -Dwanaku.service.registration.announce-address=<your-public-address> \
     -jar <service-jar-file>.jar
NOTE
Each downstream MCP server may have its own specific set of configurations. For example, the Camel Integration Capability for Wanaku requires additional properties to connect to different systems. Always consult the specific documentation for the service you are using for more details.
Running Archetype-Generated Services Locally (No Authentication)
Services scaffolded with wanaku services create tool or wanaku services create resource include OIDC authentication by default. When running against a local router in noauth mode, the service fails at startup because it tries to contact a non-existent Keycloak server. To run locally without authentication, reaugment the service to disable OIDC, then start it:
java -Dquarkus.launch.rebuild=true -Dquarkus.oidc-client.enabled=false -jar target/quarkus-app/quarkus-run.jarThen start normally (adjust port and router URL as needed):
java -Dquarkus.http.port=9010 -Dwanaku.service.registration.uri=http://localhost:8080 -jar target/quarkus-app/quarkus-run.jarThis reaugmentation step is only needed once per build. The augmentation layer change persists until the next mvn clean package.
Prerequisites
Before deploying Wanaku on OpenShift, ensure you have:
- Access to an OpenShift or Kubernetes cluster
ocorkubectlCLI tools configured- Sufficient permissions to create deployments, services, and routes
Initial Setup Steps
Deployment
You can deploy Wanaku on OpenShift or Kubernetes using the operator Helm chart.
After having deployed Keycloak, then run the following command to get its route:
kubectl get route keycloak -o jsonpath='{.spec.host}'Then install the operator and apply the custom resources with your OIDC configuration:
helm install wanaku-operator apps/wanaku-operator/deploy/helm/wanaku-operator --namespace <your-namespace>

sed -e "s/oidc-url-replace/<your-keycloak-url>/g" \
     deploy/kubernetes/wanaku-router.yaml | kubectl apply -f -

sed -e "s/oidc-url-replace/<your-keycloak-url>/g" \
    -e "s/replace-me-with-the-client-credentials-secret/<your-client-secret>/g" \
     deploy/kubernetes/wanaku-capabilities.yaml | kubectl apply -f -
Securing the Wanaku MCP Router
Security in Wanaku involves controlling access to the management APIs and web interface while ensuring that only authorized users can modify tools, resources, and configurations.
This section covers how to configure Wanaku for secure access.
NOTE
Authentication and authorization currently apply only to the management APIs and UI, not to the MCP endpoints themselves. This feature is experimental and under active development.
Understanding Wanaku Security Model
Wanaku's security model focuses on:
- API Protection: Securing management operations for tools, resources, and configuration
- UI Access Control: Restricting access to the web console
- Service Authentication: Ensuring downstream MCP servers can authenticate with the router
- MCP Authentication: Ensuring MCP calls are authenticated
MCP Authentication
Currently, Wanaku supports:
- OAuth authentication with code grant
- Automatic client registration
IMPORTANT
When using the Automatic client registration, the access is granted per-namespace. As such, applications need to request a new client id and grant if they change the namespace in use.
For these to work, Keycloak needs to be configured so that the authentication is properly supported.
Wanaku comes with a template configuration that can be imported into Keycloak to set up the realm, clients and everything else needed for Wanaku to work.
IMPORTANT
After importing this, make sure to adjust the secrets used by the services and any other potential sensitive configuration.
Configuring an MCP Client for OIDC
When connecting an MCP client application to Wanaku, you need to configure it with the correct OIDC client ID and scopes. By default, the Wanaku Keycloak realm provides the following settings for MCP clients:
- Client ID:
mcp-client - Scopes:
openid,wanaku-mcp-client
When an application uses these settings to connect to a Wanaku MCP endpoint, the user will be redirected to the Keycloak login page. After entering their username and password, Keycloak will redirect them back to the application with a valid authentication token.
NOTE
If using automatic client registration, the registered client will use these same defaults. Applications only need to request a new client ID and grant when changing the namespace in use.
Configuring Wanaku Components for Secure Access
Each Wanaku component requires a specific set of configurations for secure access. You can find the full set of configuration options in the Configuration Guide.
The configuration varies depending on the component's role in the system.
Wanaku Router Backend Security Configurations
The backend service handles API operations and requires OIDC configuration with service credentials. Some of the configurations you may need to change are:
# Address of the Keycloak authentication server - adjust to your Keycloak instance
auth.server=http://localhost:8543
# Address used by the OIDC proxy -
auth.proxy=http://localhost:${quarkus.http.port}

# Client identifier configured in Keycloak for the backend service
quarkus.oidc.client-id=wanaku-mcp-router

# Avoid forcing HTTPS
quarkus.oidc.resource-metadata.force-https-scheme=false
References
As a reference for understanding what is going on under the hood, the following guides may be helpful:
Downstream MCP Server Security Configurations
Wanaku also requires downstream MCP servers to be authenticated in order to register themselves. Downstream MCP servers act as OIDC clients and authenticate with the router using client credentials. Some of the settings you may need to adjust are:
# Address of the Keycloak authentication server - adjust to your Keycloak instance
auth.server=http://localhost:8543

# Keycloak realm name - adjust to your Keycloak realm (default: wanaku)
auth.realm=${AUTH_REALM:wanaku}

# Address of the Keycloak authentication server
quarkus.oidc-client.auth-server-url=${auth.server}/realms/${auth.realm}

# Client secret from Keycloak for service authentication - replace with your actual secret
quarkus.oidc-client.credentials.secret=aBqsU3EzUPCHumf9sTK5sanxXkB0yFtv
IMPORTANT
- Downstream MCP servers use the OIDC client component (
quarkus.oidc-client.*), which differs from the main router configuration - The client secret values shown here are examples from the default configuration - replace them with your actual Keycloak client secrets
- Ensure the auth-server-url points to your actual Keycloak instance
Encrypting Secrets at Rest
Wanaku supports AES-256 encryption for secrets stored in files. When enabled, all secrets provisioned by tools and resources are encrypted before being written to disk and automatically decrypted when read.
To enable secret encryption, set both environment variables:
export WANAKU_SECRETS_ENCRYPTION_PASSWORD="your-strong-password"
export WANAKU_SECRETS_ENCRYPTION_SALT="unique-salt-value"
IMPORTANT
- Both password and salt must be set for encryption to work
- All services that handle secrets must use the same password and salt values
- Store credentials securely (e.g., Kubernetes Secrets, HashiCorp Vault)
WARNING
If the encryption password or salt is lost, encrypted secrets cannot be recovered. Ensure these values are backed up securely.
For more details, see the Configuration Guide.
Using the Wanaku MCP Router
Protocol Support
Wanaku supports MCP via SSE (deprecated) or via Streamable HTTP.
The MCP endpoint exposed by Wanaku can be accessed on the path /mcp/sse of the host you are using (for instance, if running locally, that would mean http://localhost:8080/mcp/sse).
The Streamable HTTP endpoint can be accessed on the path /mcp/.
IMPORTANT
Also make sure to check the details about namespaces, as Wanaku offers different namespaces where MCP Tools and MCP Resources can be registered. This is documented further ahead in this guide.
CLI Authentication
The Wanaku CLI supports authentication to securely interact with the Wanaku MCP Router API. Authentication credentials are stored locally and automatically included in API requests.
Authentication Modes
The CLI currently supports the following authentication modes:
- token (default): Use an API token for authentication via Bearer token
- username and password
Authentication Commands
Login
Store authentication credentials for use with subsequent CLI commands:
wanaku auth login --api-token <your-api-token>Options:
--api-token <token>: API token for authentication--auth-server <url>: Authentication server URL (optional)--username <username>: Username for password-based login--password <password>: Password for password-based login (interactive)--realm <realm>: Keycloak realm for direct Keycloak authentication (optional; when omitted, uses the router OIDC proxy)--client-id <client-id>: OAuth2 client ID (default:admin-cli)--mode <mode>: Authentication mode -tokenoroauth2(default:token)
Discovery URL behavior:
- When
--realmis provided, the CLI constructs a Keycloak-native OIDC discovery URL:<auth-server>/realms/<realm>/.well-known/openid-configuration - When
--realmis omitted (or blank), the CLI falls back to the Wanaku router OIDC proxy path:<auth-server>/q/oidc/.well-known/openid-configuration - This allows
wanaku auth loginto work directly against a Keycloak instance (e.g.--auth-server http://keycloak-host --realm wanaku) as well as through the router's OIDC proxy.
Example:
wanaku auth login --api-token eyJhbGciOiJIUzI1NiIsInR5cCI6IkpXVCJ9...With custom authentication server:
wanaku auth login \
  --api-token eyJhbGciOiJIUzI1NiIsInR5cCI6IkpXVCJ9... \
  --auth-server https://keycloak.example.com \
  --mode token
With username/password directly against Keycloak:
wanaku auth login \
--auth-server http://keycloak-host \
--realm wanaku \
--username alice \
--password
With username/password through the router's OIDC proxy:
wanaku auth login \
--auth-server http://localhost:8080 \
--username alice \
--password
Status
Check the current authentication status and view stored credentials:
wanaku auth statusThis command displays:
- Current authentication mode
- Masked API token (showing first and last 4 characters)
- Authentication server URL (if configured)
- Masked refresh token (if available)
- Credentials file location
- Whether credentials are currently stored
Example output:
Authentication Status:
=====================
Mode: token
API Token: eyJh***VCJ9
Auth Server: https://keycloak.example.com
Credentials File: /Users/username/.wanaku/credentials
Has Credentials: true
Logout
Clear all stored authentication credentials:
wanaku auth logoutThis command removes all authentication data from the local credentials file.
Token Management
Manage the stored authentication token:
wanaku auth token --getBy default, --get masks the token value. Use --unmask to print the full token:
wanaku auth token --get --unmaskTo extract the token programmatically (for example, in a script or test helper), combine --unmask with --plain and capture stdout:
TOKEN=$(wanaku auth token --get --unmask --plain)You can also set or clear the stored token directly:
wanaku auth token --set <token>
wanaku auth token --clear
Using Authentication with Commands
Once authenticated via wanaku auth login, all subsequent CLI commands will automatically include the authentication token in their requests.
Per-Command Token Override
You can override the stored authentication token for a single command:
wanaku tools list --token <temporary-token>Disabling Authentication
To explicitly disable authentication for a command:
wanaku tools list --no-authCredential Storage
By default, credentials are stored in:
~/.wanaku/credentialsYou can override this path with the WANAKU_CREDENTIALS environment variable to isolate credentials across contexts or concurrent sessions:
export WANAKU_CREDENTIALS=/tmp/my-isolated-credentials
wanaku auth login --api-token <token>
This is useful when running multiple test plans or sessions in parallel, as it prevents token overwrites that would otherwise occur in the shared global file.
The credentials file is a Java properties file containing:
api.token: The API bearer tokenrefresh.token: OAuth2 refresh token (when applicable)auth.mode: The authentication mode (token, oauth2, etc.)auth.server.url: The authentication server URL
CAUTION
The credentials file contains sensitive authentication tokens. Ensure proper file permissions are set to prevent unauthorized access. On Unix-like systems, you should restrict access: chmod 600 ~/.wanaku/credentials
Authentication Flow
The CLI authentication process works as follows:
- Login: User provides API token via
wanaku auth login --api-token <token> - Storage: Token is stored in
~/.wanaku/credentials - Auto-Injection: The CLI automatically reads the token and adds it as a Bearer token to the
Authorizationheader for all API requests - Validation: The Wanaku Router validates the token on each request
- Logout: User can clear credentials via
wanaku auth logout
Troubleshooting Authentication
Token Not Working
If you receive authentication errors:
Check token validity:
shellwanaku auth statusVerify the token hasn't expired
Ensure you're using the correct authentication server URL
Try logging in again with a fresh token
Clear and Reset
To completely reset authentication:
wanaku auth logout
wanaku auth login --api-token <new-token>
Manual Credential Management
You can manually edit or remove the credentials file if needed:
# View credentials
cat ~/.wanaku/credentials

# Remove credentials manually
rm ~/.wanaku/credentials
Security Best Practices
- Token Protection: Never share your API tokens or commit them to version control
- Regular Rotation: Rotate tokens periodically for enhanced security
- Use Environment Variables: For CI/CD, consider using
--tokenflag with environment variables instead of storing tokens - File Permissions: Ensure credentials file has restricted permissions (600)
- Logout When Done: Use
wanaku auth logoutwhen finished working on shared systems
Example Workflows
Basic Authentication Workflow
# Login with API token
wanaku auth login --api-token eyJhbGciOiJIUzI1NiIsInR5cCI6IkpXVCJ9...

# Verify authentication
wanaku auth status

# Use authenticated commands
wanaku tools list
wanaku resources list
wanaku data-store list

# Logout when done
wanaku auth logout
CI/CD Usage
For automated scripts, use token override instead of storing credentials:
# Use token from environment variable
wanaku tools list --token $WANAKU_API_TOKEN

# Or disable authentication for public endpoints
wanaku tools list --no-auth
Admin Commands
The standalone wanaku-keycloak-admin binary provides Keycloak administration operations for managing realms, users, and service client credentials. These commands authenticate directly against Keycloak using admin credentials rather than the user's stored token.
Common Options
All admin commands share the following options:
| Option | Description | Default |
|---|---|---|
--admin-username | Admin username for Keycloak (required unless WANAKU_ADMIN_USERNAME is set) | |
--admin-password | Admin password for Keycloak (required unless WANAKU_ADMIN_PASSWORD is set, interactive) | |
--keycloak-url | Keycloak server URL | http://localhost:8543 |
--realm | Keycloak realm to manage | wanaku |
If you prefer not to pass admin credentials on every command, set them once in your environment:
export WANAKU_ADMIN_USERNAME=admin
export WANAKU_ADMIN_PASSWORD=admin
wanaku-keycloak-admin users list
User Management
# List all users in the realm
wanaku-keycloak-admin users list --admin-username admin --admin-password admin

# Create a new user (email, first-name, last-name are optional and default to username-based values)
# By default, the email is marked as verified (equivalent to passing --verified).
# Use --no-verified to leave it unverified, but note that emailVerified must be true
# for OIDC login to succeed; otherwise Keycloak returns "account_not_fully_set_up"
# and the CLI throws ServiceAuthException: Account is not fully set up.
wanaku-keycloak-admin users add --admin-username admin --admin-password admin \
  --username alice --password secretpass \
  --email alice@example.com --first-name Alice --last-name Smith

# Create a user with an unverified email
wanaku-keycloak-admin users add --admin-username admin --admin-password admin \
  --username bob --password secretpass --no-verified

# Remove a user
wanaku-keycloak-admin users remove --admin-username admin --admin-password admin \
  --username alice

# Set a user's password
wanaku-keycloak-admin users set-password --admin-username admin --admin-password admin \
  --username alice --password newpass
Service Client Credential Management
# List service clients (filters out internal Keycloak clients)
wanaku-keycloak-admin credentials list --admin-username admin --admin-password admin

# Create a new service client
wanaku-keycloak-admin credentials add --admin-username admin --admin-password admin \
  --client-id my-service --description "My service client"

# Create a service client and display its secret
wanaku-keycloak-admin credentials add --admin-username admin --admin-password admin \
  --client-id my-service --show-secret

# Show an existing client's secret
wanaku-keycloak-admin credentials show --admin-username admin --admin-password admin \
  --client-id my-service --show-secret

# Regenerate a client's secret
wanaku-keycloak-admin credentials regenerate --admin-username admin --admin-password admin \
  --client-id my-service --show-secret

# Remove a service client
wanaku-keycloak-admin credentials remove --admin-username admin --admin-password admin \
  --client-id my-service
Note: The
--show-secretflag is required to display client secrets. Without it,credentials showwill print a warning instead. Use with caution as secrets may leak into logs or shell history.
Realm Management
# Import the default realm configuration (deploy/auth/wanaku-config.json)
wanaku-keycloak-admin realm create --admin-username admin --admin-password admin

# Import a custom realm configuration file
wanaku-keycloak-admin realm create --admin-username admin --admin-password admin \
  --config /path/to/realm.json

# Import with a custom Keycloak URL
wanaku-keycloak-admin realm create --keycloak-url http://keycloak:8080 \
  --admin-username admin --admin-password admin
Understanding How Wanaku Connects to Downstream MCP Servers
Wanaku itself does not have any builtin MCP tool, resource or functionality itself. The router itself is just a blank MCP server.
To actually perform its work, Wanaku connects to downstream MCP servers that provide the connectivity bridge enabling Wanaku to talk to any kind of service. At its core, Wanaku is powered by Quarkus and Apache Camel, which provide the ability to connect to more than 300 different types of systems and services.
The power of Wanaku relies on its ability to plug in different types of systems, regardless of them being new microservices or legacy enterprise systems. For instance, consider the scenario of an enterprise organization, which is running hundreds of systems. With Wanaku, it is possible to create a specific downstream MCP server for each of them (i.e.: one for the finance systems, another for human resources, another for billing, and so on).
The granularity on which these downstream MCP servers can operate is a decision left to the administrator of the system. For some organizations, having a "Kafka" MCP server connected to Wanaku capable of talking to any of its systems may be enough. Others, may want to have system-specific ones (i.e.: a billing service, an employee system service, etc).
The recommended way to create those downstream MCP servers is to use the Camel Integration Capability for Wanaku. This is a subcomponent of Wanaku that leverages Apache Camel to exchange data with any system that Camel is capable of talking to.

NOTE
Downstream MCP servers were, at some point, also called "capabilities", "downstream services", or "targets". You may still see that terminology used in some places, especially in older documentation.
The registered downstream MCP servers determine what type of tools you may add to the router.
Wanaku classifies downstream MCP servers into the following types:
tool-invoker: these MCP servers provide MCP tools.resource-provider: these MCP servers provide MCP resources.multi-capability: these MCP servers provide both MCP tools and MCP resources.
Managing MCP Tools
An MCP (Model Context Protocol) tool enables Large Language Models (LLMs) to execute tasks beyond their inherent capabilities by using external functions. Each tool is uniquely identified by a name and defined with an input schema that outlines the expected parameters. Essentially, MCP tools act as a standardized interface through which an AI agent can request information or execute specific tasks from external systems, like APIs or databases.
Tools and resources are managed through MCP servers added to the router. When you register an MCP server, its tools become available automatically. The CLI provides read-only commands for inspecting tools.
Listing Tools
Any available tool is listed by default when you access the UI.
When using the CLI, the wanaku tools list command allows you to view all available tools on your Wanaku MCP Router instance.
Running this command will display a comprehensive list of tools, including their names and descriptions.
wanaku tools listFor example, you should receive an output similar to this.
Name               Type               URI
meow-facts      => http            => https://meowfacts.herokuapp.com?count={parameter.valueOrElse('count', 1)}
dog-facts       => http            => https://dogapi.dog/api/v2/facts?limit={parameter.valueOrElse('count', 1)}
Showing Tool Details
The wanaku tools show command displays detailed information about a specific tool registered in the Wanaku MCP Router.
wanaku tools show <tool-name>This command retrieves comprehensive details including the tool's name, namespace, type, description, URI, labels, and input schema properties.
Example:
wanaku tools show meow-factsSample Output:
Tool Details:
name        meow-facts
namespace   default
type        http
description Retrieve random facts about cats
uri         https://meowfacts.herokuapp.com?count={parameter.valueOrElse('count', 1)}
labels      category=animals

Input Schema Properties:
name   type   description                    required
count  int    The count of facts to retrieve yes
Options:
--host <url>: The API host URL (default:http://localhost:8080)
Example with remote host:
wanaku tools show --host http://api.example.com:8080 meow-factsGenerating Tools
The wanaku tools generate command converts an OpenAPI specification into a collection of tool references that can be used by an AI agent.
It parses and resolves OpenAPI paths and operations, transforming them into a standardized tool reference format for HTTP services.
This command accepts an OpenAPI specification file (either as a local path or URL) and produces a JSON output containing tool references.
Each operation in the API is converted to a tool reference with appropriate metadata, including the operation's name, description, URI template, and input schema.
The command handles server variable substitution, proper formatting of path parameters according to the tool reference specification.
By default, the command uses the first server defined in the OpenAPI specification, but you can override this behavior by specifying a different server URL or selecting a different server from the specification by index.
The generated output can be directed to standard output or saved to a file.
If the process completes successfully, the command returns exit code 0. It returns exit code 3 if no paths are found in the specification and exit code 2 if an error occurs during processing.
NOTE
The command support both json and yaml definition:
For example:
wanaku tools generate http://petstore3.swagger.io/api/v3/openapi.yamlIf the spec defines a server url that contains variables
servers:
  - url: 'https://{env}.domain.com/foo/{v1}/{v2}/{v3}'
    variables:
      env:
        description: Environment - staging or production
        default: stage-api
        enum:
          - stage-api
          - api
      # other variables
      # ...
Then, you can specify values as command parameters:
wanaku tools generate --server-variable env=prod --server-variable v1=first http://petstore3.swagger.io/api/v3/openapi.jsonIf not specified for a variable in the server URL template, the default value defined in the OpenAPI specification will be used.
It only applies when using servers from the OpenAPI specification (not when using --server-url).
Variables must be defined in the server object of the OpenAPI specification.
Empty or null values for either key or value will be ignored.
OpenAPI specifications can define multiple server URLs:
{
  "servers": [
    {
      "url": "https://api.example.com/v1",
      "description": "Production server"
    },
    {
      "url": "https://staging-api.example.com/v1",
      "description": "Staging server"
    },
    {
      "url": "http://localhost:8080/v1",
      "description": "Local development server"
    }
  ]
}
The --server-index (or -i) option allows you to specify which server definition from the OpenAPI specification should be used as the base URL for tool references.
wanaku tools generate -i 1 ./openapi-spec.yamlThis option is ignored if --server-url is specified, as an explicit URL overrides any server definitions in the specification.
If neither --server-index nor --server-url is specified, the command will default to using the first server (index 0) from the specification.
The --server-index option can be used together with --server-variable when the selected server has variable templates:
servers:
  - url: https://{environment}.api.example.com/{version}
    variables:
      environment:
        default: dev
      version:
        default: v1
  - url: https://{environment}.api2.example.com/{version}
    variables:
      environment:
        default: dev
      version:
        default: v1
  - url: https://{environment}.api3.example.com/{version}
    variables:
      environment:
        default: dev
      version:
        default: v1
You could select this server and override its variables:
wanaku tools generate -i 0 -v environment=prod -v version=v2 ./openapi-spec.yamlThe --output-file (or -o) option specifies the file path where the generated tool references should be written.
It determines where the output JSON containing all the tool references will be saved.
wanaku tools generate -o ./tools/api-tools.json http://petstore3.swagger.io/api/v3/openapi.jsonIf --output-file is specified, the command will write the JSON tool references to the specified file path.
If --output-file is not specified, the command will write the JSON tool references to standard output (STDOUT).
If the specified path is a directory, the command will write to a file named out.json within that directory and provide a warning message.
If the specified file already exists, the command will return an error without overwriting the file. The parent directory of the specified file must exist and be writable by the current user.
Managing MCP Resources
Resources are managed through MCP servers added to the router. The CLI provides read-only commands for inspecting resources.
Listing Resources
The wanaku resources list command allows you to view all resources currently exposed by your Wanaku MCP Router instance.
Executing this command will display a list of available resources, including their names and descriptions.
wanaku resources listShowing Resource Details
The wanaku resources show command displays detailed information about a specific resource registered in the Wanaku MCP Router.
wanaku resources show <resource-name>This command retrieves comprehensive details including the resource's name, type, description, location, MIME type, namespace, labels, and parameters.
Example:
wanaku resources show q4-reportSample Output:
Resource Details:
name        q4-report
type        file
description Q4 Financial Report
location    /home/user/documents/report.pdf
mimeType    application/pdf
namespace   default
labels      category=finance, year=2024

Parameters:
name   value
key1   value1
key2   value2
Options:
--host <url>: The API host URL (default:http://localhost:8080)
Example with remote host:
wanaku resources show --host http://api.example.com:8080 q4-reportManaging MCP Prompts
Prompts are reusable templates that can leverage multiple tools and provide example interactions for LLMs. They are part of the MCP (Model Context Protocol) specification and enable:
- Creating standardized message templates with variable substitution
- Defining argument schemas for dynamic prompt generation
- Referencing tools that the prompt can utilize
- Supporting multiple content types (text, images, audio, embedded resources)
- Providing example interactions to guide LLM behavior
Adding Prompts Using the UI
You can manage prompts through the Wanaku Web UI:
- Navigate to the Prompts page in the Web UI
- Click "Add Prompt"
- Fill in the form:
- Name: Unique identifier for the prompt
- Description: Human-readable description
- Messages (JSON): Array of message objects
- Arguments (JSON): Array of argument objects (optional)
- Tool References (JSON): Array of tool names (optional)
- Namespace: Namespace for isolation (optional)
Example message JSON formats:
Text Message:
{
  "role": "user",
  "content": {
    "type": "text",
    "text": "Review {{code}}"
  }
}
Image Message:
{
  "role": "user",
  "content": {
    "type": "image",
    "data": "iVBORw0KGgoAAAANSUhEUgAAAAUA...",
    "mimeType": "image/png"
  }
}
Audio Message:
{
  "role": "user",
  "content": {
    "type": "audio",
    "data": "UklGRiQAAABXQVZFZm10IBAAAA...",
    "mimeType": "audio/wav"
  }
}
Embedded Resource Message:
{
  "role": "user",
  "content": {
    "type": "resource",
    "resource": {
      "location": "file:///path/to/file.txt",
      "description": "File content",
      "mimeType": "text/plain"
    }
  }
}
Listing Prompts
View all prompts currently available in your Wanaku MCP Router instance:
wanaku prompts listThis displays all prompts with their names, descriptions, and namespaces.
Managing Shared Data
Wanaku provides a data store feature that allows you to share static data between Wanaku and its downstream MCP servers.
This is particularly useful for storing configuration files, route definitions, and other static resources that downstream MCP servers need to access at runtime.
A primary use case for the data store is storing Apache Camel routes and associated files for the Camel Integration Capability.
By storing route definitions in the data store, you can dynamically configure integrations without rebuilding or redeploying services.
IMPORTANT
Authentication is required to access the data store API. Make sure you're logged in using wanaku auth login before using data store commands.
Adding Data to the Data Store
The wanaku data-store add command allows you to upload files to the data store. Files are automatically Base64 encoded when stored.
wanaku data-store add --read-from-file /path/to/file.yamlBy default, the data store entry will be named after the filename. You can specify a custom name using the --name option:
wanaku data-store add --read-from-file /path/to/employee-routes.camel.yaml --name employee-routesIn this example:
--read-from-file: Specifies the local file path to upload--name: (Optional) Assigns a custom name to the stored data
The file contents are automatically Base64 encoded before being sent to the server, ensuring binary-safe storage.
Listing Stored Data
View all data currently stored in the data store:
wanaku data-store listThis displays a table showing:
- ID: Unique identifier for each stored item
- Name: The name of the stored data
- Data: A preview of the stored content (truncated to 50 characters)
- Labels: Labels associated with the data store entry
You can filter the list using label expressions:
# Filter by label expression
wanaku data-store list -e 'category=routes'
See the label expression guide (wanaku man label-expression) for detailed syntax information.
Managing Labels on Data Stores
Data stores support labels for organization and filtering, similar to tools and resources.
Adding labels to a data store:
# Add labels to a specific data store by ID
wanaku data-store label add --id <data-store-id> --label category=routes --label env=production

# Add labels to multiple data stores using label expressions
wanaku data-store label add -e 'category=config' --label migrated=true
Removing labels from a data store:
# Remove labels from a specific data store by ID
wanaku data-store label remove --id <data-store-id> --label temporary --label draft

# Remove labels from multiple data stores using label expressions
wanaku data-store label remove -e 'status=deprecated' --label legacy
When adding a label with a key that already exists, the value will be updated. When removing a non-existent label, it will be silently ignored.
Removing Data from the Data Store
Remove stored data using either the ID or name:
# Remove by ID
wanaku data-store remove --id <data-store-id>

# Remove by name
wanaku data-store remove --name employee-routes
NOTE
The data store is also accessible via the REST API at /api/v1/data-store and through the Wanaku web interface under the Data Stores page, where you can upload, download, and manage stored data using a graphical interface.
Managing Service Catalogs
Service catalogs provide a way to package, distribute, and deploy complete integration services to the Wanaku router. A service catalog bundles Camel routes, Wanaku rules, and optional dependencies into a single ZIP package that can be deployed as a unit. This is especially useful for teams that want to share pre-built integrations or automate the deployment of complex multi-route services.
For comprehensive documentation on service catalogs — including structure, CLI workflow, Kubernetes deployment, and REST API reference — see the Service Catalogs Guide.
Quick Start
# 1. Initialize the catalog structure
wanaku service init --name=hr-system --services=employees,payroll

# 2. Edit the Camel routes
#    (modify hr-system/employees/employees.camel.yaml)
#    (modify hr-system/payroll/payroll.camel.yaml)

# 3. Generate rules from routes
wanaku service expose --path=hr-system

# 4. Deploy to the router
wanaku service deploy --path=hr-system --host=http://localhost:8080
See Service Catalogs Guide for details on structure, packaging, operator deployment, and REST API usage.
TIP
If you need parameterized, reusable service catalogs, see Service Templates for details on creating and instantiating templates.
Configuring Downstream MCP Servers
Configurations in Wanaku have two distinct scopes:
- Downstream MCP server configurations
- Tool definition configurations
Downstream MCP Server Configurations
These configurations are essential for setting up the downstream MCP server itself.
This includes details required for the transport mechanism used to access the service, such as usernames and passwords for authenticating with the underlying system that provides the service.
Each downstream MCP server may have its own specific set of configurations. As such, check the service documentation for details.
Tool Definition Configurations
These configurations are specific to individual tools that leverage a particular downstream MCP server. They include:
- Names and identifiers that differentiate tools using the same downstream MCP server, like specific Kafka topics or the names of database tables.
- Operational properties that dictate how the tool behaves, such as the type of HTTP method (
GET,POST,PUT), or operational settings like timeout configurations and idempotence flags.
These configurations are handled when adding a new tool to Wanaku MCP Router.
NOTE
Check the "Configuring Downstream MCP Servers" section for additional details about this.
Accessing Other MCP servers (MCP Forwards)
The MCP bridge in Wanaku allows it to act as a central gateway or proxy to other MCP servers that use HTTP as the transport mechanism.
This feature enables a centralized endpoint for aggregating tools and resources provided by other MCP servers.
Listing Forwards
To view a list of currently configured forwards, use the wanaku forwards list command:
wanaku forwards listThis command displays information about each forward, including its name, service URL, and any other relevant details.
This can be useful for managing and troubleshooting MCP server integrations.
Adding Forwards
To add an external MCP server to the Wanaku instance, use the wanaku forwards add command:
wanaku forwards add --service="http://your-mcp-server.com:8080/mcp/sse" --name my-mcp-server--service: The URL of the external MCP server's SSE (Server-Sent Events) endpoint.--name: A unique human-readable name for the forward, used for identification and management purposes.--namespace/-N(required): The namespace name to associate the forward with (e.g.,public,default). The CLI resolves the name to its UUID automatically.--namespace-id(alternative to--namespace): The namespace UUID to use directly, for scripting or when the UUID is already known.
Use --namespace for the common case (human-readable name), or --namespace-id when scripting with known UUIDs. These options are mutually exclusive.
Once a forward is added, all tools and resources provided by the external MCP server will be mapped in the Wanaku instance.
These tools and resources can then be accessed as if they were local to the server.
Removing Forwards
To remove a specific external MCP server from the Wanaku instance, use the wanaku forwards remove command:
wanaku forwards remove --name my-mcp-server--name: The human-readable name for the forward to be removed.
WARNING
Forward removal operations cannot be undone. Once removed, the tools and resources from those MCP servers will no longer be accessible.
NOTE
Attempting to remove a non-existent forward will result in an error message.
Example Use Case
Suppose you have two MCP servers: http://mcp-server1.com:8080/mcp/sse and http://mcp-server2.com:8080/mcp/sse.
To integrate these external MCP servers into your Wanaku instance, follow these steps:
- Add the first forward using the
wanaku forwards addcommand:
wanaku forwards add --service="http://mcp-server1.com:8080/mcp/sse" --name mcp-server-1- Use the
wanaku forwards listcommand to confirm that the forward has been successfully added:
wanaku forwards list- Verify that all tools and resources from
mcp-server1are now accessible within your Wanaku instance usingwanaku tools list
Name               Type               URI
tavily-search-local => tavily          => tavily://search?maxResults={parameter.value('maxResults')}
meow-facts      => mcp-remote-tool => <remote>
dog-facts       => mcp-remote-tool => <remote>
camel-rider-quote-generator => mcp-remote-tool => <remote>
tavily-search   => mcp-remote-tool => <remote>
laptop-order => mcp-remote-tool => <remote>- Add the second forward using the same command:
wanaku forwards add --service="http://mcp-server2.com:8080/mcp/sse" --name mcp-server-2- Confirm that tools and resources from both external MCP servers are now integrated into your Wanaku instance (use
wanaku tools list) - Use the
wanaku forwards listcommand to view the updated list of forwards:
wanaku forwards listBy leveraging the MCP bridge feature, you can create a centralized endpoint for aggregating tools and resources from multiple external MCP servers, simplifying management and increasing the overall functionality of your Wanaku instance.
Managing Namespaces
Wanaku introduces the concept of namespaces to help users organize and isolate tools and resources, effectively managing the Large Language Model (LLM) context. This prevents context bloat and improves the efficiency of your Wanaku deployments.
What Are Namespaces
Namespaces provide a mechanism to group related tools and resources.
Each namespace acts as a separate logical container, ensuring that the LLM context for tools within one namespace does not interfere with tools in another. This is particularly useful when you have a large number of tools or when different sets of tools are used for distinct purposes.
Wanaku provides a fixed set of 10 available slots for namespaces, named from ns-0 to ns-9. It also provides a default namespace, which is used if none is specified and a special public namespace that can be accessed without any authentication.
Using Namespaces
Tools and resources are associated with namespaces through the MCP servers that provide them.
Wanaku automatically associates namespace names with available numerical slots from ns-0 to ns-9.
All commands that accept --namespace (-N) also support --namespace-id for passing the namespace UUID directly. These options are mutually exclusive. Use --namespace-id when scripting with known UUIDs.
Checking Namespace Assignments
You can verify which namespace a tool or resource has been assigned to by using the wanaku namespaces list command.
This command will display a list of all active namespaces, their unique IDs, and their corresponding paths.
The output will look similar to this:
id                                   name   path
28560e66-d94c-44a2-b032-779b5542132a        http://localhost:8080/ns-4/mcp/sse
43b5d7a7-4e7d-4109-960b-ac7695b6f2d3 public http://localhost:8080/public/mcp/sse
93c5bfdf-0e09-4da5-82fa-4eec3bf6b1b4        http://localhost:8080/ns-3/mcp/sse
bfd112d2-32cb-475a-9f55-63301519152b        http://localhost:8080/ns-7/mcp/sse
f5915650-4daa-4616-95c6-5aafceffb026        http://localhost:8080/ns-1/mcp/sse
db89fedd-ffe6-4dee-b051-bcd5285bb9c9        http://localhost:8080/ns-2/mcp/sse
d4249e11-9368-4c5b-bb66-981d2d2e69c7        http://localhost:8080/ns-0/mcp/sse
8898fab6-3774-427f-8400-8c6f6fd9a97e        http://localhost:8080/ns-6/mcp/sse
fe8cc1f2-2355-4009-ba68-4faeefe937f7        http://localhost:8080/ns-5/mcp/sse
a3dfaaf6-3655-4bcc-8c48-3d183b6d675b        http://localhost:8080/ns-8/mcp/sse
8832e2c7-3bd9-4f9b-88ba-982cc20a43de        http://localhost:8080/ns-9/mcp/sse
<default>                                   http://localhost:8080//mcp/sse
In this output, you can see the mapping of internal namespace IDs to their corresponding ns-X paths.
IMPORTANT
For Streamable HTTP, remove the /sse from the path (i.e.: http://localhost:8080/ns-1/mcp/).
The Default Namespace
If you do not specify a namespace when adding a tool or resource, it will automatically be added to the default namespace.
The default namespace acts as a general container for tools that don't require specific isolation.
You can identify the default namespace in the wanaku namespaces list output by its <default> name.
Filtering Namespaces by Labels
You can filter namespaces by their labels when listing them:
# List all namespaces with a specific label
wanaku namespaces list --label-filter 'env=production'

# List namespaces matching complex expressions
wanaku namespaces list --label-filter 'env=production & tier=backend'
See the Label Expressions Guide for detailed information on the label expression syntax and advanced filtering options.
Shell Completion
Wanaku provides shell completion support for bash and zsh, enabling tab-completion for all commands, subcommands, and their options. This significantly improves the command-line experience by reducing typing and helping discover available commands and options.
Generating Completion Scripts
To generate a completion script, use the wanaku completion generate command:
# Generate completion script and output to stdout
wanaku completion generate

# Save completion script to a file
wanaku completion generate --output ~/.wanaku_completion
The generated script includes completion support for:
- All parent commands (namespaces, tools, resources, forwards, etc.)
- All subcommands (namespaces list, tools list, etc.)
- All command options (--help, --verbose, --plain, command-specific options)
- Automatic detection of bash vs zsh shell
Quick Setup for Current Session Only
If you want to enable completion for just your current terminal session without making permanent changes:
# One-liner for bash or zsh (works on both Linux and macOS)
source <(wanaku completion generate)

# Alternative using eval (also works on both bash and zsh)
eval "$(wanaku completion generate)"
This generates and immediately sources the completion script in your current shell. Completion will be active until you close the terminal, without creating any files or modifying your shell configuration files.
This is useful for:
- Testing completion before permanent installation
- Temporary/one-time use
- Environments where you don't want to modify shell configuration
Installing Completion on Linux
For Bash
- Generate the completion script to a standard location:
wanaku completion generate --output /etc/bash_completion.d/wanaku_completion- Add the following line to your
~/.bashrc:
source /etc/bash_completion.d/wanaku_completion- Reload your shell:
source ~/.bashrcAlternatively, for user-specific installation:
wanaku completion generate --output ~/.wanaku_completion
echo "source ~/.wanaku_completion" >> ~/.bashrc
source ~/.bashrc
For Zsh
- Generate the completion script:
mkdir -p ~/.zsh/completions
wanaku completion generate --output ~/.zsh/completions/_wanaku- Add the following lines to your
~/.zshrc:
autoload -U +X bashcompinit && bashcompinit
source ~/.zsh/completions/_wanaku- Reload your shell:
source ~/.zshrcInstalling Completion on macOS
For Zsh (Default on macOS Catalina and later)
- Generate the completion script:
mkdir -p ~/.zsh/completions
wanaku completion generate --output ~/.zsh/completions/_wanaku- Add the following lines to your
~/.zshrc:
autoload -U +X bashcompinit && bashcompinit
source ~/.zsh/completions/_wanaku- Reload your shell:
source ~/.zshrcFor Bash (If using bash on macOS)
- Generate the completion script:
wanaku completion generate --output /usr/local/etc/bash_completion.d/wanaku- Add the following line to your
~/.bash_profile:
source /usr/local/etc/bash_completion.d/wanaku- Reload your shell:
source ~/.bash_profileUsing Shell Completion
Once installed, you can use tab-completion with the Wanaku CLI:
# Tab-complete commands
wanaku <TAB>
# Shows: admin, auth, completion, configure, datastores, forwards, man, mcp, namespaces, prompts, resources, service, start, tools

# Tab-complete subcommands
wanaku namespaces <TAB>
# Shows: cleanup, create, delete, list, show

# Tab-complete options
wanaku tools list --<TAB>
# Shows: --help, --host, --plain, --verbose

# Tab-complete after partial input
wanaku name<TAB>
# Completes to: wanaku namespaces
Troubleshooting
If completion doesn't work after installation:
Verify the script was sourced: Check that your shell configuration file (
.bashrc,.zshrc, or.bash_profile) contains the source command and was reloaded.Check shell detection: The completion script automatically detects whether you're using bash or zsh. Verify you're using a supported shell:
shellecho $BASH_VERSION # For bash echo $ZSH_VERSION # For zshManually source the script: Try sourcing the completion script directly:
shellsource ~/.wanaku_completionRegenerate the script: If you've updated Wanaku and new commands aren't appearing, regenerate the completion script:
shellwanaku completion generate --output ~/.wanaku_completion source ~/.wanaku_completion
Limitations
- PowerShell: Shell completion is not currently supported for PowerShell on Windows. Users on Windows should use WSL (Windows Subsystem for Linux) with bash or zsh for completion support.
- Fish shell: Fish shell is not supported by picocli 4.7.7. Only bash and zsh are supported.
Understanding URIs
Universal Resource Identifiers (URI) are central to Wanaku.
They are used to define the location of resources, the tool invocation request that Wanaku will receive from the Agent/LLM and the location of configuration and secret properties.
Understanding URIs is critical to leverage Wanaku and create flexible definitions of tools and resources.
Flexible Input Data
Some services may require a more flexible definition of input data.
For instance, consider HTTP endpoints with dynamic parameters:
http://my-host/api/{someId}http://my-host/api/{someId}/createhttp://my-host/api/{someId}/link/to/{anotherId}
In cases where the service cannot predetermine the actual tool addresses, users must define them when creating the tool.
Creating URIs
Building the URIs is not always as simple as defining their address. Sometimes, optional parameters need to be filtered out or query parameters need to be built. To help with that, Wanaku comes with a couple of expressions to build them.
To access the values, you can use the expression {parameter.value('name')}. For instance, to get the value of the parameter id you would use the expression {parameter.value('id')}. You can also provide default values if none are provided, such as http://my-host/{parameter.valueOrElse('id', 1)}/data (this would provide the value 1 if the parameter id is not set).
It is also possible to build the query part of URIs with the query method. For instance, to create a URI such as http://my-host/data?id=456 you could use http://my-host/data{parameter.query('id')}. If the id parameter is not provided, this would generate a URI such as http://my-host/data. This can take multiple parameters, so it is possible to pass extra variables such as {parameter.query('id', 'name', 'location', ...)}.
IMPORTANT
Do not provide the ? character. It is added automatically the parsing code if necessary.
Building the query part of URIs can be quite complex if there are too many. To avoid that, you can use {parameter.query} to build a query composed of all query parameters.
The values for the queries will be automatically encoded, so a URI defined as http://my-host/{parameter.query('id', 'name')} would generate http://my-host/?id=456&name=My+Name+With+Spaces if provided with a name value of "My Name With Spaces".
Dealing with Request Bodies
The wanaku_body property is a special argument used to indicate that the associated property or argument should be included in the body of the data exchange, rather than as a parameter.
For instance, in an HTTP call, wanaku_body specifies that the property should be part of the HTTP body, not the HTTP URI.
The handling of such parameters may vary depending on the service being used.
Passing Metadata as Headers
The wanaku_meta_ prefix is a special argument prefix that allows AI services to inject headers into tool invocations without requiring changes to the tool's configuration or route definition.
Arguments with this prefix are:
- Extracted from the regular arguments (they are not passed to the tool as arguments)
- Stripped of the
wanaku_meta_prefix - Forwarded as headers in the tool invocation request
For example, an argument named wanaku_meta_contextId with value ctx-123 becomes a header with key contextId and value ctx-123.
This is useful for passing context information (such as user IDs, session IDs, or correlation IDs) from the AI service through to the downstream MCP server.
Example: LangChain4j AI Service
@RegisterAiService
public interface MyService {
    @McpToolBox("toolbox")
    String callTool(
        @Header("wanaku_meta_contextId") String contextId,
        @Header("wanaku_meta_userId") String userId,
        @UserMessage String message
    );
}
In the tool implementation, these become accessible as headers in the ToolInvokeRequest:
Map<String, String> headers = request.getHeadersMap();
String contextId = headers.get("contextId");  // prefix stripped
String userId = headers.get("userId");
NOTE
If a metadata header has the same name as a tool-defined header (from the tool's schema), the tool-defined header takes precedence.
Passing Authentication Tokens as Headers
The wanaku_auth_ prefix is a special argument prefix that allows MCP clients to propagate access tokens or other credentials to downstream MCP servers without exposing them to LLMs.
Arguments with this prefix are:
- Extracted from the regular arguments (they are never passed to LLMs or to the tool as arguments)
- Stripped of the
wanaku_auth_prefix - Forwarded as headers in the tool invocation request
- Always redacted in logs and observability events
For example, an argument named wanaku_auth_Authorization with value Bearer token-123 becomes a header with key Authorization and value Bearer token-123.
This is useful for propagating access tokens from MCP clients through to downstream MCP servers (HTTP, Camel, etc.) when calling protected third-party APIs.
Security Guarantees
Unlike wanaku_meta_, authentication arguments have stricter security handling:
- Never exposed to LLMs — filtered from tool arguments before any processing
- Never appear in events — filtered from observability event arguments
- Always redacted in headers — sensitive header names (e.g.,
Authorization) are redacted in event headers - Highest merge priority — auth headers override both metadata and tool-defined headers on conflict
Example: HTTP Service with Protected API
To call a protected third-party API (e.g., GitHub), the MCP client passes the access token via wanaku_auth_:
Arguments from MCP client:
  wanaku_auth_Authorization = "Bearer ghp_xxxxxxxxxxxx"
  owner = "octocat"
  repo = "hello-world"
The wanaku_auth_Authorization argument is extracted and becomes an Authorization header on the outgoing HTTP request, while owner and repo are passed as regular tool arguments.
Example: Multiple Auth Tokens
Multiple auth tokens can be propagated simultaneously:
Arguments from MCP client:
  wanaku_auth_Authorization = "Bearer internal-token"
  wanaku_auth_X-Third-Party-Token = "external-token"
Both are extracted and forwarded as separate headers to the downstream MCP server.
Reserved Argument Names
Currently special arguments:
wanaku_body- Indicates the argument should be included in the request bodywanaku_meta_- Prefix for arguments that are converted to headers (e.g.,wanaku_meta_contextId)wanaku_auth_- Prefix for sensitive authentication arguments that are converted to headers with redaction (e.g.,wanaku_auth_Authorization)
Extending Wanaku: Adding Your Own Downstream MCP Servers
Wanaku leverages Quarkus and Apache Camel to provide connectivity to a vast range of services and platforms.
Although we aim to provide a few of them out-of-the box, not all of them will fit all the use cases. For most cases, users should rely on the Camel Integration Capability for Wanaku. That service leverages Apache Camel which offers more than 300 components capable of talking to any type of system. Users can design their integrations using tools such as Kaoto or Karavan and expose the routes as tools or resources using that service.
Adding a New Resource Provider
For cases where the Camel Integration Capability for Wanaku is not sufficient, users can create their own downstream MCP servers.
We try to make it simple for users to create custom services that solve their particular needs.
Creating a New Resource Provider
To create a custom resource provider, you can run:
mvn -B archetype:generate \
  -DarchetypeGroupId=ai.wanaku \
  -DarchetypeArtifactId=wanaku-provider-archetype \
  -DgroupId=ai.wanaku \
  -DartifactId=wanaku-provider-y4 \
  -Dname=Y4
To run the newly created service enter the directory that was created (i.e.,; cd wanaku-provider-y4), then build the project using Maven (mvn clean package).
NOTE
Downstream MCP servers are created, by default, using Apache Camel. However, it is possible to create purely Quarkus-based services by adding -Dwanaku-capability-type=quarkus to the Maven command.
Then, launch it using:
java -Dwanaku.service.registration.uri=http://localhost:8080 -Dquarkus.http.port=9901 ... -jar target/quarkus-app/quarkus-run.jarYou can check if the service was registered correctly by viewing the downstream MCP servers in the admin UI.
IMPORTANT
Remember to set the parameters in the application.properties file and also adjust the authentication settings.
Adjusting Your Resource Provider
After created, then most of the work is to adjust the auto-generated Delegate class to provide the Camel-based URI and, if necessary, coerce (convert) the response from its specific type to String.
Adding a New Tool Service
Creating a New Tool Service
To create a custom tool service, you can run:
mvn -B archetype:generate \
  -DarchetypeGroupId=ai.wanaku \
  -DarchetypeArtifactId=wanaku-tool-service-archetype \
  -DgroupId=ai.wanaku \
  -DartifactId=wanaku-tool-service-jms \
  -Dname=Jms
NOTE
Downstream MCP servers are created, by default, using Apache Camel. However, it is possible to create purely Quarkus-based services by adding -Dwanaku-capability-type=quarkus to the Maven command.
To run the newly created service enter the directory that was created (i.e.,; cd wanaku-tool-service-jms), then build the project using Maven (mvn clean package).
Then, launch it using:
java -Dwanaku.service.registration.uri=http://localhost:8080 -Dquarkus.http.port=9900 ... -jar target/quarkus-app/quarkus-run.jarYou can check if the service was registered correctly by viewing the downstream MCP servers in the admin UI.
IMPORTANT
Remember to set the parameters in the application.properties file and also adjust the authentication settings.
To customize your service, adjust the delegate and client classes.
Adjusting Your Tool Service
After created, then most of the work is to adjust the auto-generated Delegate and Client classes to invoke the service and provide the returned response.
In those cases, then you also need to write a class that leverages Apache Camel's ProducerTemplate and (or, sometimes, both) ConsumerTemplate to interact with the system you are implementing connectivity to.
Adding a New MCP Server
Creating a New Mcp server
To create a custom mcp server, you can run:
mvn -B archetype:generate \
  -DarchetypeGroupId=ai.wanaku \
  -DarchetypeArtifactId=wanaku-mcp-servers-archetype \
  -DgroupId=ai.wanaku \
  -DartifactId=wanaku-mcp-servers-s3 \
  -Dname=S3
To run the newly created service enter the directory that was created (i.e.,; cd wanaku-mcp-servers-s3), then build the project using Maven (mvn clean package).
NOTE
Downstream MCP servers are created, by default, using Apache Camel. However, it is possible to create purely Quarkus-based services by adding -Dwanaku-capability-type=quarkus to the Maven command.
Then, launch it using:
java -Dwanaku.service.registration.uri=http://localhost:8080 -Dquarkus.http.port=9901 ... -jar target/quarkus-app/quarkus-run.jarYou can check if the service was registered correctly using wanaku forwards list.
IMPORTANT
Remember to set the parameters in the application.properties file.
Adjusting Your MCP Server
After created, then most of the work is to adjust the auto-generated Tool class to implement the mcp server tool.
Implementing Services in Other Languages
Wanaku uses MCP for communication between the router and downstream MCP servers. Therefore, it's possible to implement services in any language that supports MCP.
Adjusting the announcement address
You can adjust the address used to announce to the MCP Router using either (depending on whether using a tool or a resource provider):
wanaku.service.registration.announce-address=my-host
This is particularly helpful when running a downstream MCP server in the cloud, behind a proxy or firewall.
Adjusting the authentication parameters
quarkus.oidc-client.auth-server-url=http://localhost:8543/realms/${auth.realm}(realm defaults towanaku; configure viaAUTH_REALM)quarkus.oidc-client.client-id=wanaku-servicequarkus.oidc-client.refresh-token-time-skew=1mquarkus.oidc-client.credentials.secret=<insert key here>
Supported/Tested Clients
Wanaku implements the MCP protocol and, by definition, should support any client that is compliant to the protocol.
The details below describe how Wanaku MCP router can be used with some prominent MCP clients:
Embedded LLMChat for testing
The Wanaku Praxis router includes an embedded LLMChat page for quick testing of tools.
NOTE
The LLMChat feature is part of the Wanaku Praxis admin UI.
- Setup LLM -
baseurl,api key,model, and extra parameters - Select tools
- Enter prompt and send
Creating New MCP Server Using Maven
IMPORTANT
When using the maven way, please make sure to adjust the version of Wanaku to be used by correctly setting the wanaku-version property to the base Wanaku version to use.
Adjusting the MCP Server
After creating the mcp server, open the pom.xml file to add the dependencies for your project. Using the example above, we would include the following dependencies:
    <dependency>
      <groupId>org.apache.camel.quarkus</groupId>
      <artifactId>camel-quarkus-aws-s3</artifactId>
    </dependency>
Adjust the port in the application.properties file by adjusting the quarkus.http.port property.
NOTE
You can also provide the port when launching (i.e., java -Dquarkus.http.port=9190 -jar target/quarkus-app/quarkus-run.jar)
Then, build the project:
mvn clean packageAnd run it:
java -jar target/quarkus-app/quarkus-run.jarClaude
You can let the CLI generate the Claude Desktop configuration for you:
wanaku configure claudeThis updates the claude_desktop_config.json file and configures Claude Desktop to connect directly to Wanaku via HTTP. If your Wanaku server is exposing streamable HTTP instead of SSE, use --transport http.
{
  "mcpServers": {
    "wanaku": {
      "url": "http://localhost:8080/mcp/sse/"
    }
  }
}
Cursor
Cursor can connect directly to Wanaku over HTTP or SSE. The CLI will update the Cursor MCP config for you:
wanaku configure cursor --transport http --port 8080Cursor stores its global MCP config in ~/.cursor/mcp.json and the command will merge the wanaku entry without removing existing servers.
HyperChat
Wanaku works with HyperChat. To do so, you can configure Wanaku as an MCP server using the MCP configuration as shown below:

IMPORTANT
Make sure to have Wanaku up and running before configuring HyperChat. You may also need to close and reopen HyperChat.
After configuring HyperChat, you may need to go the Main Window and edit any existing agent if you have any. Then, in the agent configuration Window, in the allowMCPs option, make sure you mark Wanaku as an allowed MCP server. If in doubt, check the HyperChat project documentation.
NOTE
Older versions of HyperChat (pre 1.1.13) required manually editing the mcp.json file as described on the improvement ticket. This is not necessary for newer versions.
LibreChat
For LibreChat search for mcpServers on the librechat.yml file and include something similar to this:
mcpServers:
    everything:
        url: http://host.docker.internal:8080/mcp/sse
IMPORTANT
Make sure to point to the correct address of your Wanaku MCP instance.
In LibreChat, you can access Wanaku MCP tools using Agents.
Witsy
We also have tested Wanaku with Witsy - AI Desktop Assistant.
Using an STDIO gateway
Wanaku does not support stdio. Therefore, to use Wanaku with to use it with tools that don't support SSE, it is necessary to use an stdio-to-SSE gateway. The application super gateway can be used for this.
npx -y supergateway --sse http://localhost:8080/mcp/sseAvailable Resources and Tools
NOTE
Most users should rely on the Camel Integration Capability for Wanaku to create tools and resources. For custom implementations beyond Camel's connectivity, you can use the Wanaku Capabilities Java SDK.
API Note
All CLI commands use the Wanaku management API under the hood. If you need more advanced functionality or want to automate tasks, you may be able to use this API directly.
By using these CLI commands, you can manage resources and tools for your Wanaku MCP Router instance.
Troubleshooting
TIP
If you are setting up Wanaku for the first time, see the First-Run Troubleshooting Guide for the most common setup issues (authentication, service registration, Docker Compose, SDK, and deployment).
This section provides solutions to common issues you may encounter while using Wanaku.
Authentication Issues
Cannot authenticate with the router
Symptoms:
- CLI commands fail with authentication errors
- Web UI redirects to Keycloak but login fails
Solutions:
Verify Keycloak is running and accessible:
shellcurl http://localhost:8543/healthCheck that the Keycloak realm is properly configured:
- Ensure the
wanakurealm exists - Verify the
wanaku-mcp-routerclient is configured - Confirm user accounts have been created
- Ensure the
Clear stored credentials and re-authenticate:
shellrm ~/.wanaku/credentials wanaku auth login \ --auth-server http://localhost:8080 \ --username alice \ --passwordVerify the router can reach Keycloak:
- Check the
auth.serverconfiguration property - Ensure network connectivity between components
- Check the
Token expired errors
Symptoms:
- Commands work initially but fail after some time
- Error messages about expired tokens
Solutions:
Re-authenticate with the router:
shellwanaku auth login \ --auth-server http://localhost:8080 \ --username alice \ --passwordCheck token lifetime settings in Keycloak if tokens expire too quickly
Service Registration Issues
Downstream MCP servers not appearing in the router
Symptoms:
- Services start successfully but don't show up in the admin UI
- Tools or resources from a service are not available
Solutions:
Verify the service registration configuration:
shell# In the downstream MCP server application.properties wanaku.service.registration.enabled=true wanaku.service.registration.uri=http://localhost:8080Check service logs for registration errors:
shell# Look for registration-related errors grep -i "registration" /path/to/service.logVerify network connectivity between the service and router:
shell# From the service host curl http://localhost:8080/q/healthCheck if the service is using the correct OIDC credentials:
- Verify
quarkus.oidc-client.credentials.secretmatches the secret in Keycloak - Ensure the
wanaku-serviceclient exists in Keycloak
- Verify
Check the router backend logs for incoming registration requests
Service shows as "offline" or "unhealthy"
Symptoms:
- Service appears in the admin UI but marked as offline
- Intermittent availability
Solutions:
Verify the service is running:
shell# Check if the port is listening netstat -an | grep 9009Check the registration interval and ensure heartbeats are being sent:
shell# In application.properties wanaku.service.registration.interval=10sReview service health and ensure it's not crashing or restarting
Connection Issues
Cannot connect to the router from MCP clients
Symptoms:
- MCP clients fail to connect
- Timeout errors when connecting
Solutions:
Verify the router is running and accessible:
shellcurl http://localhost:8080/q/healthCheck the correct MCP endpoint is being used:
- SSE transport:
http://localhost:8080/mcp/sse - Streamable HTTP:
http://localhost:8080/mcp/
- SSE transport:
For namespace-specific connections, ensure the correct path:
shell# For namespace ns-1 http://localhost:8080/ns-1/mcp/sseVerify firewall rules allow traffic on port 8080
Check CORS settings if connecting from a web application:
shellquarkus.http.cors.enabled=true quarkus.http.cors.origins=http://localhost:3000
Tool and Resource Issues
Tools or resources not appearing in MCP clients
Symptoms:
wanaku tools listshows tools, but they don't appear in the MCP client- Resources are registered but not accessible
Solutions:
Verify the tool/resource is in the correct namespace:
shellwanaku tools list wanaku namespaces listCheck if the client is connected to the correct namespace endpoint
Refresh the MCP client connection
Verify the downstream MCP server providing the tool is online by checking the admin UI
Tool invocation fails
Symptoms:
- Tool appears in client but execution fails
- Error messages when calling a tool
Solutions:
Check the tool URI is correct:
shellwanaku tools listVerify the downstream MCP server is running and healthy
Review service logs for errors during tool execution
Ensure required configuration or secrets are properly set:
shellwanaku tools listFor HTTP tools, verify the target endpoint is accessible from the service
Resource read fails
Symptoms:
- Resource appears but cannot be read
- Empty or error responses when accessing resources
Solutions:
Verify the resource URI and that the target exists:
shellwanaku resources listCheck file permissions if using file-based resources
Verify network access if using remote resources (S3, FTP, etc.)
Review provider service logs for errors
Build and Deployment Issues
Build fails with missing dependencies
Symptoms:
- Maven build errors
- Missing artifact errors
Solutions:
Ensure you're using the correct Maven version:
shellmvn --version # Should be 3.xClear Maven cache and rebuild:
shellrm -rf ~/.m2/repository/ai/wanaku mvn clean installVerify internet connectivity for downloading dependencies
Native build fails
Symptoms:
- Native compilation errors
- GraalVM-related failures
Solutions:
Verify GraalVM is properly installed:
shelljava -version # Should show GraalVM native-image --versionCheck the Quarkus native build guide for system requirements
Try building without native mode first to isolate the issue:
shellmvn clean package
Container deployment fails
Symptoms:
- Pods in CrashLoopBackOff state
- ImagePullBackOff errors
Solutions:
Verify the container image exists and is accessible:
shellpodman pull quay.io/wanaku/wanaku-barn-backend:latestCheck pod logs for startup errors:
shellkubectl logs <pod-name>Verify ConfigMaps and Secrets are properly mounted:
shellkubectl describe pod <pod-name>Check resource limits and ensure sufficient memory/CPU
Verify Keycloak is accessible from the pods:
shellkubectl exec <pod-name> -- curl http://keycloak:8080/health
Performance Issues
Slow response times
Symptoms:
- Tools take a long time to execute
- Resource reads are slow
- MCP clients experience timeouts
Solutions:
Check router and service resource usage:
shelltop htopReview logs for errors or warnings
Verify network latency between components:
shellping <service-host>Check Infinispan cache performance and consider adjusting:
shellwanaku.infinispan.max-state-count=10For Kubernetes deployments, ensure adequate resource limits:
yamlresources: requests: memory: "512Mi" cpu: "500m" limits: memory: "1Gi" cpu: "1000m"
Logging and Debugging
Enable debug logging
To get more detailed logs for troubleshooting:
Router backend:
quarkus.log.level=DEBUG
quarkus.log.category."ai.wanaku".level=DEBUG
quarkus.mcp.server.traffic-logging.enabled=true
Downstream MCP servers:
quarkus.log.level=DEBUG
quarkus.log.category."ai.wanaku".level=DEBUG
CLI:
wanaku --verbose tools listTo produce clean, parsable output without ANSI colors or escape sequences (useful for scripting and piping):
wanaku tools list --plainAccess logs
Check logs in these locations:
- Router backend: Look for
wanaku-barn-backend.logor check container logs - Downstream MCP servers: Check individual service log files
- Kubernetes:
kubectl logs <pod-name>
Getting Help
If you continue to experience issues:
- Check the GitHub Issues for similar problems
- Review the documentation
- Join the community discussions
- Open a new issue with:
- Wanaku version
- Deployment environment (local, OpenShift, etc.)
- Steps to reproduce
- Relevant log excerpts
- Configuration (with secrets redacted)